

2026 Valid DY0-001 Exam Updates - 2026 Study Guide
DY0-001 Certification - The Ultimate Guide [Updated 2026]
CompTIA DY0-001 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 14
Which of the following distance metrics for KNN is best described as a straight line?
- A. Manhattan
- B. Radial
- C. Euclidean
- D. Cosine
Answer: C
Explanation:
# Euclidean distance is the most intuitive distance metric. It measures the shortest "straight-line" distance between two points in Euclidean space. This is typically used in KNN and clustering when features are continuous and appropriately scaled.
Why the other options are incorrect:
* A: "Radial" isn't a standard distance metric; may refer vaguely to radial basis functions.
* C: Cosine measures the angle (orientation) between vectors - not straight-line distance.
* D: Manhattan distance sums the absolute differences across dimensions - visualized as block-like (taxicab) paths, not direct lines.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.4:"Euclidean distance is the default metric in KNN for measuring straight-line proximity in feature space."
* Data Mining Techniques, Chapter 3:"Euclidean distance represents the shortest path between two points and is widely used in distance-based learning algorithms."
-
NEW QUESTION # 15
A data scientist would like to model a complex phenomenon using a large data set composed of categorical, discrete, and continuous variables. After completing exploratory data analysis, the data scientist is reasonably certain that no linear relationship exists between the predictors and the target. Although the phenomenon is complex, the data scientist still wants to maintain the highest possible degree of interpretability in the final model. Which of the following algorithms best meets this objective?
- A. Decision tree
- B. Random forest
- C. Multiple linear regression
- D. Artificial neural network
Answer: A
Explanation:
Decision trees capture complex, nonlinear relationships with a transparent, rule-based structure. They remain highly interpretable (each split can be visualized and explained) unlike ensembles (random forests) or neural networks, and they don't rely on linear assumptions.
NEW QUESTION # 16
A data scientist is merging two tables. Table 1 contains employee IDs and roles. Table 2 contains employee IDs and team assignments. Which of the following is the best technique to combine these data sets?
- A. outer join between Table 1 and Table 2
- B. inner join between Table 1 and Table 2
- C. left join on Table 1 with Table 2
- D. right join on Table 1 with Table 2
Answer: B
Explanation:
# An inner join returns only those records that have matching keys (employee IDs in this case) in both tables.
Since each table provides a different attribute for the same entity (employee), an inner join is the most efficient and accurate method when focusing on employees present in both tables.
Why the other options are less ideal:
* B & C: Left or right joins would include unmatched data, which may lead to nulls.
* D: An outer join brings in all records from both tables and fills nulls where no matches exist, which may introduce irrelevant or incomplete entries.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.2:"Inner joins are most appropriate when combining datasets with matching keys to retain only relevant, intersecting records."
* SQL for Data Analysts, Chapter 3:"Use inner joins when combining tables on a common key to include only matched data for analysis."
-
NEW QUESTION # 17
A data scientist is using the following confusion matrix to assess model performance: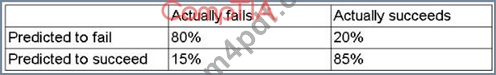
The model is predicting whether a delivery truck will be able to make 200 scheduled delivery stops. Every time the model is correct, the company saves an hour in planning and scheduling of maintenance work. Every time the model is wrong, the company loses four hours of delivery time for the truck. Which of the following is the net model impact for the company?
- A. 25 hours saved
- B. 165 hours lost
- C. 25 hours lost
- D. 165 hours saved
Answer: C
Explanation:
Treat each "predicted-to-fail" and "predicted-to-succeed" row as coming from 100 cases apiece (200 total).
NEW QUESTION # 18
Which of the following describes the appropriate use case for PCA?
- A. Dimensionality reduction
- B. Classification
- C. Regression
- D. Recommendation
Answer: A
Explanation:
Principal Component Analysis transforms correlated features into a smaller set of uncorrelated components that capture most of the variance, making it ideal for reducing dimensionality before modeling or visualization.
NEW QUESTION # 19
A data scientist is preparing to brief a non-technical audience that is focused on analysis and results. During the modeling process, the data scientist produced the following artifacts:
Which of the following artifacts should the data scientist include in the briefing? (Choose two.)
- A. Data dictionary
- B. Code documentation
- C. Mathematical descriptions of clustering algorithms included in the selected model
- D. Model performance statistics (accuracy, precision, recall, F1_ score, etc.)
- E. Model selection, justification, and purpose
- F. Final charts and dashboards
Answer: F
Explanation:
For a non‐technical audience centered on results, polished visualizations (charts and dashboards) and clear, high-level performance metrics (accuracy, precision, recall, F1 score) best convey the key takeaways. The deeper technical details, code docs, data dictionaries, and algorithm math, should be omitted at this level.
NEW QUESTION # 20
Which of the following is a key difference between KNN and k-means machine-learning techniques?
- A. KNN is used for finding centroids, while k-means is used for finding nearest neighbors.
- B. KNN operates exclusively on continuous data, while k-means can work with both continuous and categorical data.
- C. KNN performs better with longitudinal data sets, while k-means performs better with survey data sets.
- D. KNN is used for classification, while k-means is used for clustering.
Answer: D
Explanation:
KNN is a supervised algorithm that assigns labels based on the closest labeled examples, whereas k-means is an unsupervised method that partitions data into clusters by finding centroids without using any pre-existing labels.
NEW QUESTION # 21
Given matrix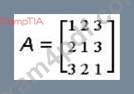
Which of the following is AT?
- A.

- B.

- C.

- D.

Answer: D
Explanation:
Transposing swaps rows and columns, so the (i, j) entry becomes the (j, i) entry.
NEW QUESTION # 22
Which of the following types of layers is used to downsample feature detection when using a convolutional neural network?
- A. Hidden
- B. Output
- C. Input
- D. Pooling
Answer: D
Explanation:
Pooling layers (such as max pooling or average pooling) reduce the spatial dimensions of the feature maps by summarizing local neighborhoods, effectively downsampling the detected features and controlling overfitting.
NEW QUESTION # 23
A data scientist has built an image recognition model that distinguishes cars from trucks. The data scientist now wants to measure the rate at which the model correctly identifies a car as a car versus when it misidentifies a truck as a car. Which of the following would best convey this information?
- A. AUC/ROC curve
- B. Correlation plot
- C. Confusion matrix
- D. Box plot
Answer: C
Explanation:
# A confusion matrix gives a detailed view of a classification model's performance, including true positives, false positives, true negatives, and false negatives. It's the best tool for examining model accuracy and misclassification between specific classes - like mislabeling trucks as cars.
Why the other options are incorrect:
* B: AUC/ROC gives a broader performance summary but not individual class misclassifications.
* C: Box plots show distributions, not classification accuracy.
* D: Correlation plots show relationships between variables - not confusion results.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.3:"Confusion matrices enable detailed analysis of classification performance and misclassification rates."
* Machine Learning Textbook, Chapter 5:"For evaluating how models classify specific classes, confusion matrices are the most direct and interpretable tool."
-
NEW QUESTION # 24
A data scientist is preparing to brief a non-technical audience that is focused on analysis and results. During the modeling process, the data scientist produced the following artifacts:
Which of the following artifacts should the data scientist include in the briefing? (Choose two.)
- A. Data dictionary
- B. Code documentation
- C. Mathematical descriptions of clustering algorithms included in the selected model
- D. Model performance statistics (accuracy, precision, recall, F1 score, etc.)
- E. Model selection, justification, and purpose
- F. Final charts and dashboards
Answer: E,F
Explanation:
# Non-technical business stakeholders value outcome-oriented visuals (charts, dashboards) and the purpose
/justification for the modeling work. These artifacts directly communicate impact without overwhelming technical complexity.
Why the other options are incorrect:
* C & D: Too technical for a non-technical audience.
* E: Useful, but may be too detailed depending on the level of abstraction desired.
* F: Data dictionary is better suited for technical handoff - not executive review.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.5:"Business-oriented presentations should emphasize clear visualizations, insights, and executive summaries of model goals."
-
NEW QUESTION # 25
A data scientist is building a model to predict customer credit scores based on information collected from reporting agencies. The model needs to automatically adjust its parameters to adapt to recent changes in the information collected. Which of the following is the best model to use?
- A. Decision tree
- B. Random forest
- C. Linear discrimination analysis
- D. XGBoost
Answer: D
Explanation:
XGBoost supports "warm-start" incremental training, continuing to refine the existing ensemble with new data, so it can automatically update its parameters as new agency information arrives. The other methods require full retraining to incorporate recent changes.
NEW QUESTION # 26
SIMULATION
A data scientist needs to determine whether product sales are impacted by other contributing factors. The client has provided the data scientist with sales and other variables in the data set.
The data scientist decides to test potential models that include other information.
INSTRUCTIONS
Part 1
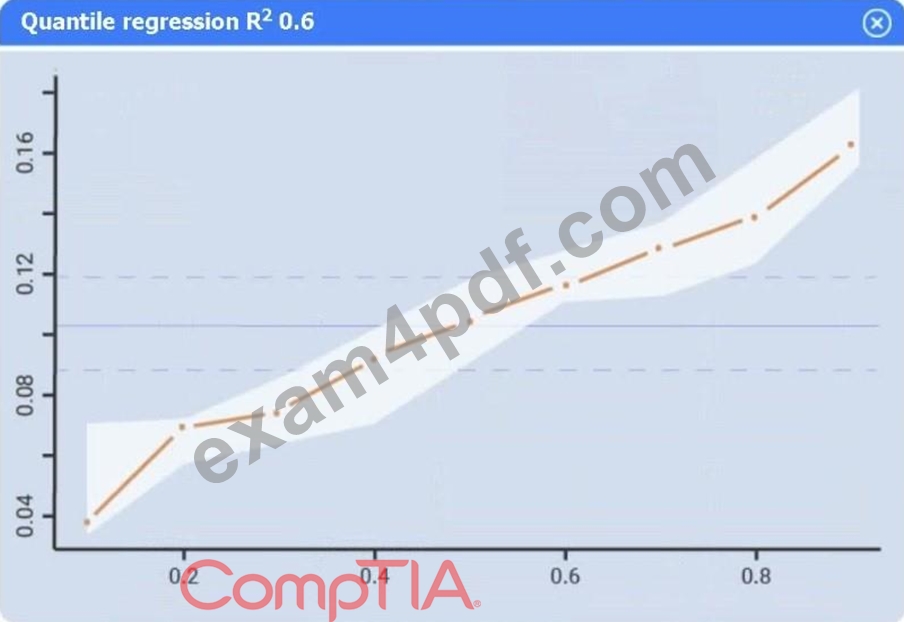
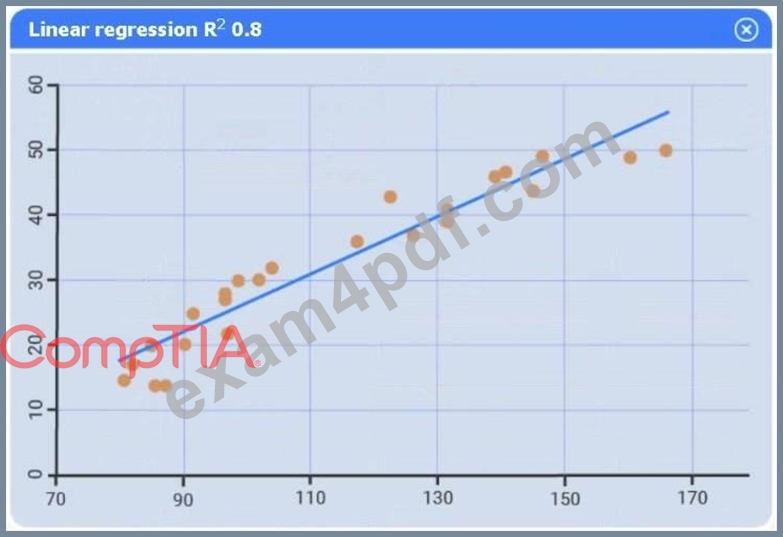
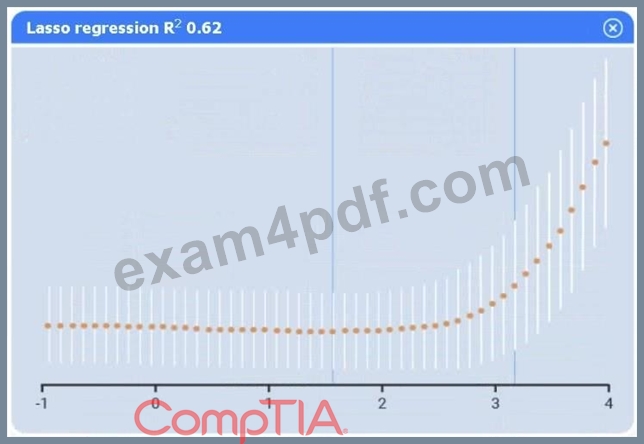
Use the information provided in the table to select the appropriate regression model.
Part 2
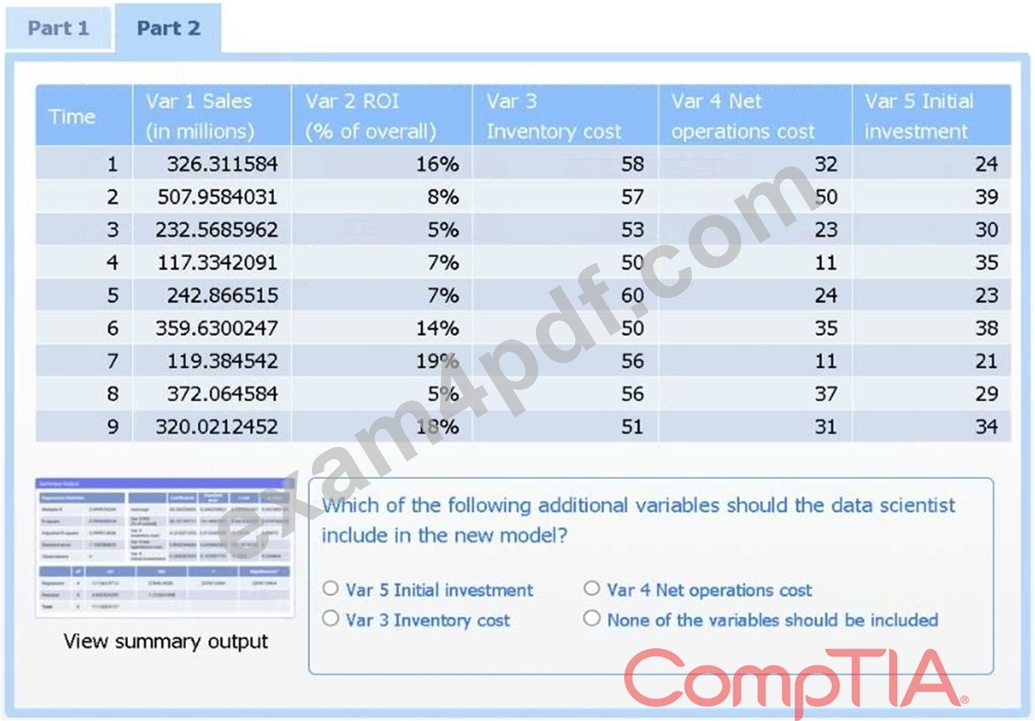
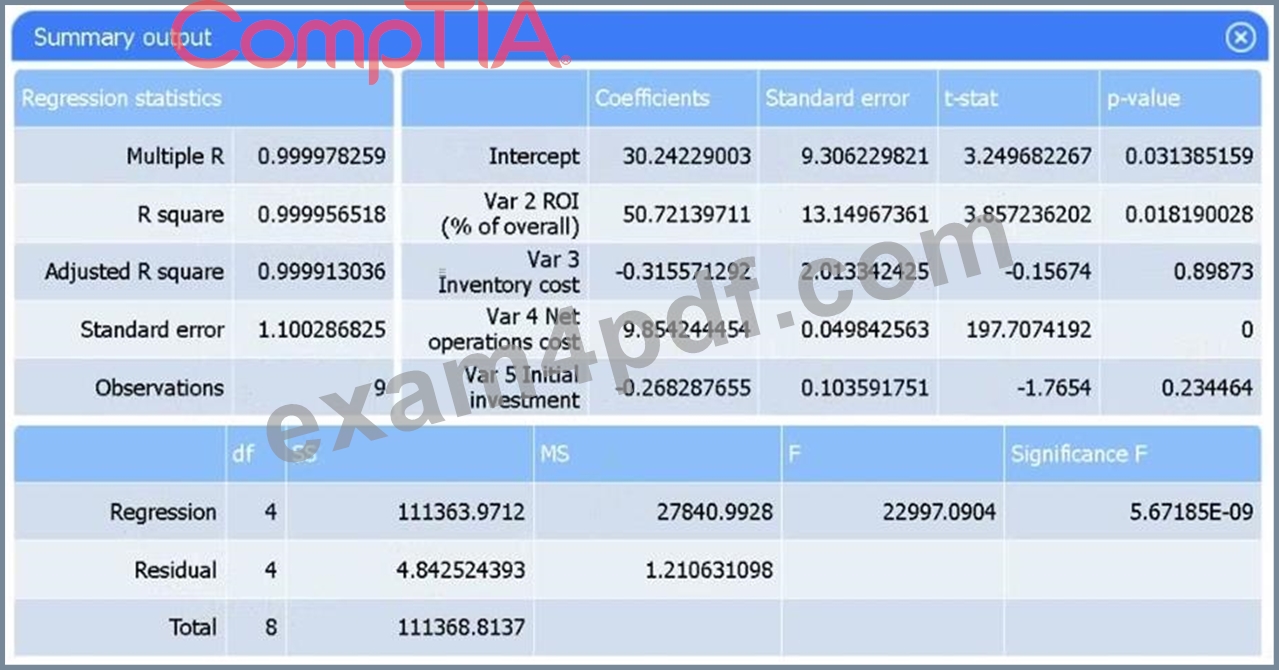
Review the summary output and variable table to determine which variable is statistically significant.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.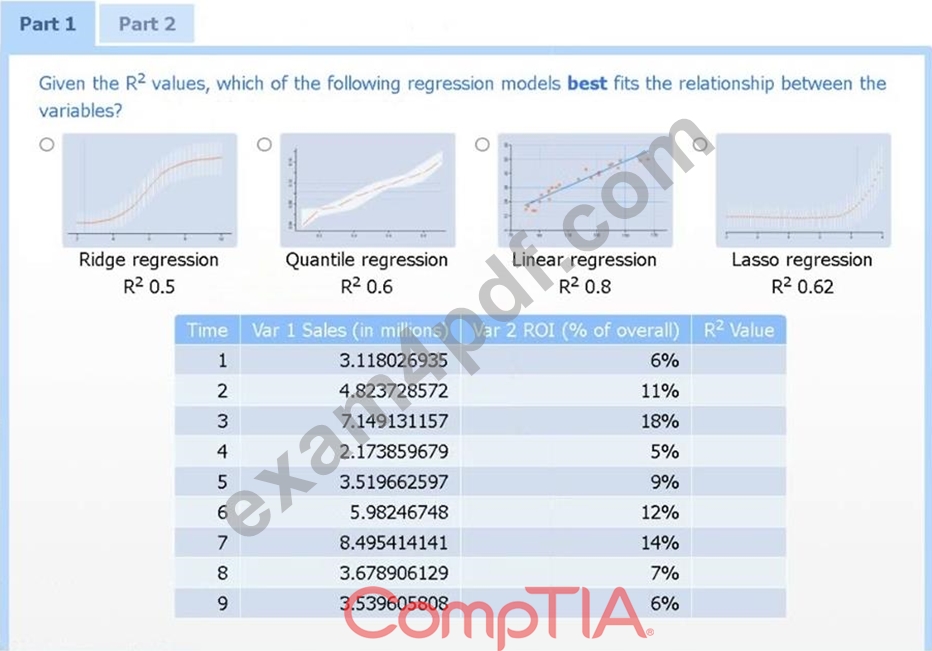
Answer:
Explanation:
Part 1
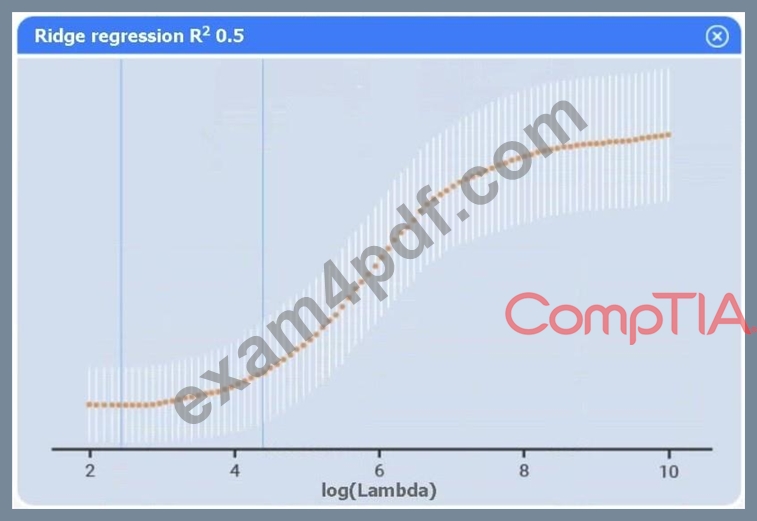
Linear regression.
Of the four models, linear regression has the highest R² (0.8), indicating it explains the greatest proportion of variance in sales.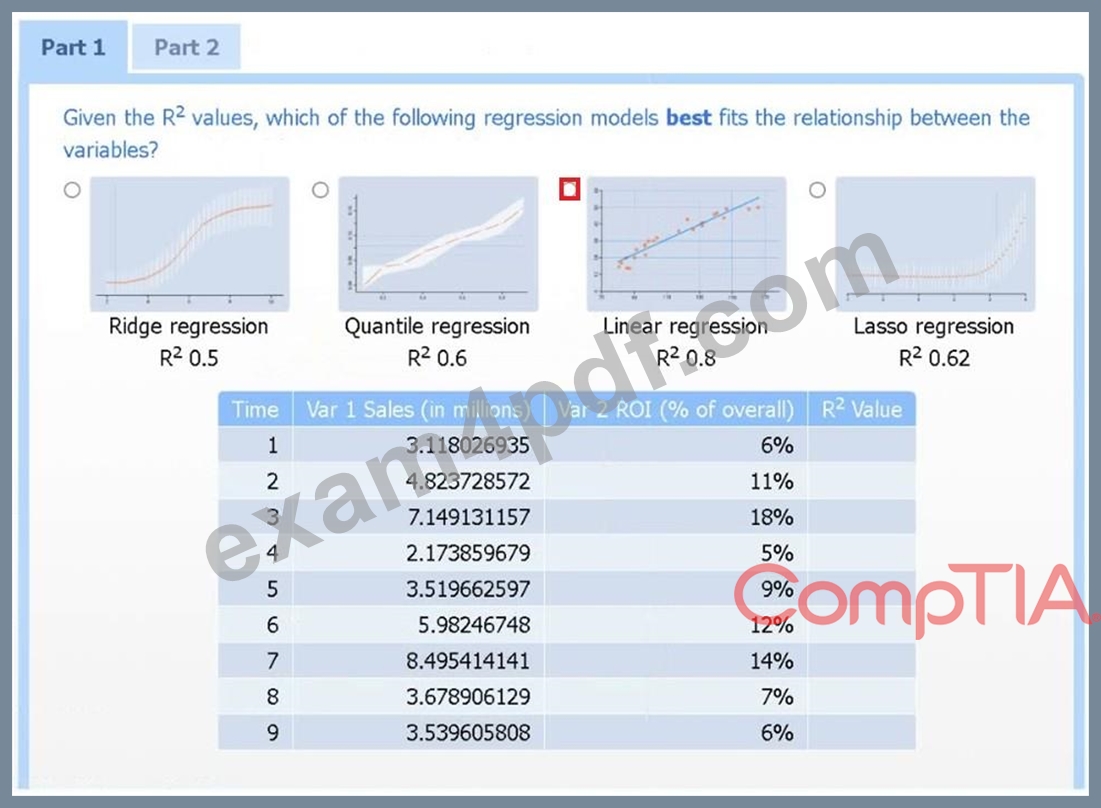
Part 2
Var 4 - Net operations cost.
Net operations cost has a p-value of essentially 0 (far below 0.05), indicating it is the only additional predictor statistically significant in explaining sales. Neither inventory cost (p≈0.90) nor initial investment (p≈0.23) reach significance.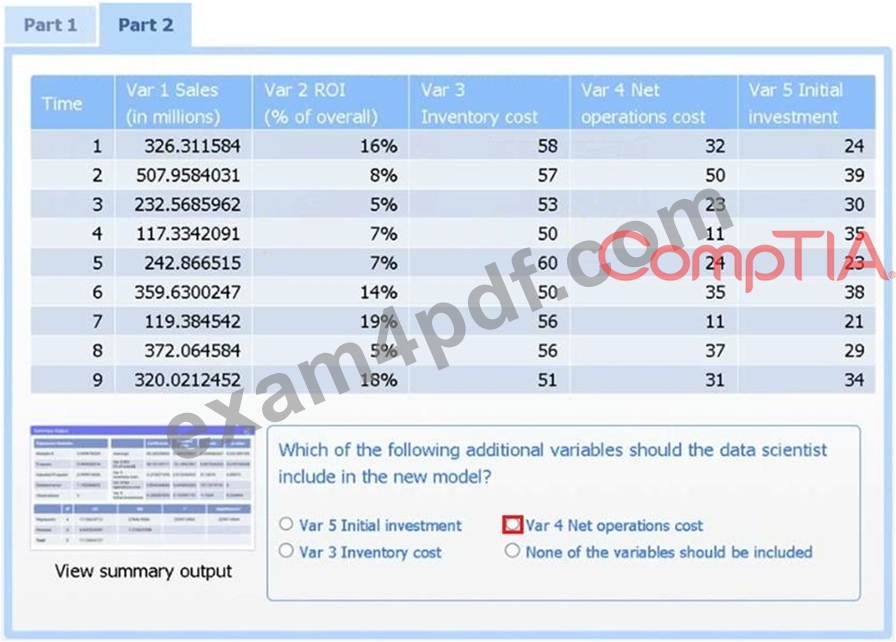
NEW QUESTION # 27
Which of the following issues should a data scientist be most concerned about when generating a synthetic data set?
- A. The data set consuming too many resources
- B. The data set having insufficient row observations
- C. The data set not being representative of the population
- D. The data set having insufficient features
Answer: C
Explanation:
If synthetic data don't accurately mirror the real-world distributions and relationships, any models trained on them will perform poorly in deployment. Representativeness is the critical concern when generating synthetic data.
NEW QUESTION # 28
A data scientist is creating a responsive model that will update a product's daily pricing based on the previous day's sales volume. Which of the following resource constraints is the data scientist's greatest concern?
- A. Deployment time
- B. Data collection time
- C. Development time
- D. Training time
Answer: D
Explanation:
# Since the model must update daily based on new data, retraining must be fast enough to meet daily deadlines. Therefore, training time is the critical constraint - it determines whether pricing updates can be executed promptly.
Why the other options are incorrect:
* A: Deployment time is a one-time or infrequent process.
* C: Development time is less critical once the model is built.
* D: Data is already collected daily - assumed to be available.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.4:"Time-sensitive applications such as daily pricing require fast model retraining, making training time a critical factor."
* Real-Time ML Deployment Handbook, Chapter 6:"Retraining time is the bottleneck in time- constrained systems that adapt to fresh inputs regularly."
-
NEW QUESTION # 29
In a modeling project, people evaluate phrases and provide reactions as the target variable for the model.
Which of the following best describes what this model is doing?
- A. TF-IDF vectorization
- B. Sentiment analysis
- C. Part-of-speech tagging
- D. Named-entity recognition
Answer: B
Explanation:
# Sentiment analysis refers to using machine learning or NLP techniques to determine the sentiment or emotional tone behind a body of text (e.g., positive, neutral, or negative). When people provide reactions to phrases, the model is learning to associate language with subjective emotion or opinion.
Why the other options are incorrect:
* B: NER identifies entities (e.g., locations, organizations) - not emotions.
* C: TF-IDF is a feature engineering method, not a modeling goal.
* D: POS tagging classifies words by their grammatical function - not sentiment.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.3:"Sentiment analysis models associate textual input with subjective labels, such as emotional response or polarity."
* Applied Text Analytics, Chapter 8:"When modeling user reactions to text, sentiment classification techniques are commonly employed."
-
NEW QUESTION # 30
......
DY0-001 Practice Exam and Study Guides - Verified By Exam4PDF: https://www.exam4pdf.com/DY0-001-dumps-torrent.html
2026 Updated Verified Pass DY0-001 Study Guides & Best Courses: https://drive.google.com/open?id=1z7YxhiUKRrXBVMRBSNn63XN5XdzcOfAo
